Category: Uncategorized
MMS • Sergio De Simone
Google’s OAuth Platform has recently introduces support for Demonstrating Proof-of-Possession (DPoP), an OAuth 2.0 security mechanism designed to mitigate token theft and replay attacks.
Traditional OAuth bearer tokens operate on a “finders-keepers” model, making them vulnerable to Infostealer malware (e.g. RedLine, NodeStealer) and Adversary-in-the-Middle (AiTM) attacks.
To prevent this types of attacks, DPoP uses cryptography to bind tokens to an asymmetric key pair generated by the client. Consequently, a stolen token cannot be replayed without the corresponding private key, which remains under the client’s control.
Google OAuth platform supports DPoP only for refresh tokens, while access tokens, which are shorter-lived, remain standard Bearer tokens. This decision is motivated by the fact that long-lived refresh tokens are “the primary vector for persistent online impersonation”, whereas applying DPoP to access tokens would introduce “asymmetric cryptographic verification overhead” for each request.
It is worth noting that adopting DPoP adds several client-side requirements, including generating cryptographic keys, handling timestamps and nonces correctly, generating the appropriate HTTP headers and the required DPoP proof JWTs.
While DPoP provides protection for API tokens, it does not protect standard web application session cookies, which remain vulnerable to Infostealer malware. To address the threat of cookie theft, Google and the Web Incubator Community Group (WICG) are developing Device Bound Session Credentials (DBSC).
DBSC operates at the browser and network layer to cryptographically bind browser session cookies to the device’s hardware (such as TPM). Together, DPoP and DBSC form a comprehensive defense-in-depth strategy against credential theft across both API and web-based user sessions.
Google also notes that DPoP is not appropriate for multi-agent workflows, as one agent cannot easily delegate a task to another agent. This would in fact require the second agent to sign requests on behalf of the first. However, this in not possible without accessing the private key generated by the first agent, which would violate DPoP. As an alternative, Google recommends developers to consider Google Cloud Secure Token Service (STS).
By routing delegation through STS, the intermediate agent can exchange the upstream token for a new, short-lived federated token cryptographically bound to its own local key pair, preserving the sender-constrained security model across the entire agent chain without key exposure.
Since the DPoP private key is stored client-side, its security ultimately depends on the security of the client itself. However, as Dhruv Agnihotri argues, single-page-apps (SPAs) running inside a browser are not entirely protected against misuse of the key. The IETF’s guidance for browser-based applications therefore recommends adopting the Backend-for-Frontend pattern to keep tokens and cryptographic keys out of the browser. Agnihotri also proposes a zero-persistence approach, which may be useful when server-side infrastructure is unavailable.
MMS • RSS
The race to turn artificial intelligence into a lasting business advantage is reshaping the software sector. Choosing potential winners requires assessing how established businesses fit into an evolving technology landscape.
BNN Bloomberg spoke with Thomas Martin, senior portfolio manager at GLOBALT Investments, about his case for Palo Alto Networks, Palantir and MongoDB.
Key Takeaways
- Evolving AI threats are driving demand for cybersecurity tools, with Martin seeing revenue potential in Palo Alto Networks’ base fees and usage-based pricing.
- Palantir’s earnings estimates have roughly doubled since its earlier share-price peak, making its valuation more attractive at a similar price, according to Martin.
- The time and money customers spend integrating Palantir’s software can make switching providers difficult and support customer retention.
- MongoDB’s work with frontier AI models and agents remains at an early stage, offering potential for rapid growth from a smaller revenue base.
- Martin expects AI competition to sustain volatility for several years and favours businesses with established customers, strong capital resources and access to skilled employees.
Read the full transcript below:
MATT: Well, it’s time now for Hot Picks, and our next guest has three companies he positions as winners in the software sector. Let’s bring in Thomas Martin, senior portfolio manager at GLOBALT Investments. Thomas, thanks for being here.
THOMAS: Great, thanks for having me on your program.
MATT: Never a dull moment in the software sector, it feels like, and so you’ve got a few for us to start, and let’s jump right into them, shall we? Palo Alto Networks is your first one, too. We kind of have seen, again, all over the place, too. But tell us why Palo Alto is on—is on your picks list for today.
THOMAS: Sure. So Palo is just one of the group of industries, I guess, that we think are attractive in AI, cybersecurity, and—but even in that unit, there’s the, you know, kind of the winners and the losers. You see that with Fortinet having reported today, and the stock’s down big, and it’s sort of dragging down Palo Alto and CrowdStrike. But Palo is a platformization—they announced that about two and a half years ago, and they’ve really been ramping that up. There’s so much change going on so quickly, what with AI and hacking going on, that they are bringing out new products constantly. And the latest one that they’re bringing up is called Continuous Frontier AI Defense, and that product is measuring and looking at things really on a continuous basis, and then they are trying to use that information to think about what the attacks are going to be and to remediate it quickly. What that means for Palo is that they will have both a base fee and then a usage-based consumption. So that should be good for their revenues.
MATT: Yeah, I was going to say. No, sorry. Keep going. Keep going, Thomas. Yeah, go ahead.
THOMAS: No, that was it. We think that they’re well positioned.
MATT: Yeah, and that’s what I was going to say. Reading a little bit about them, too, a little bit earlier, it feels like with those ones in particular that they’re still—that that ceiling is still very high as you get into some of the defence for AI, correct?
THOMAS: Absolutely, and you’re fighting against the agents that are coming and constantly making attacks. So, you know, these products are just going to continue to evolve, and they have the infrastructure to be able to offer that.
MATT: OK, next on the list is Palantir, too. I think well known to, you know, investors that are in this—in this sector a lot. But tell us why Palantir is on your list today.
THOMAS: Sure. Well, Palantir reached a high earlier this year and then really kind of went down a great deal. It’s back up near its old high, but earnings estimates have essentially doubled since then. So you have the same price, but double the earnings. So the stock is cheaper on that basis. They’re going to be the next one to report next week, and we’re expecting a good quarter out of them. You know, both in the government and in the commercial area, you know, the—the story there continues to be that they focus on ontology, and they sit at a layer in between the customers’ needs and the large language models. They focus on data sovereignty, which means that the—their customers get to keep the data, not the LLMs. And the more that you use the Palantir and the time and the money that you put into creating this ontology, the more you have sticky costs associated with it, and that makes it difficult to switch. So we think they’ll be able to continue to grow and penetrate their markets and keep their business.
MATT: Is that a unique position to be in that middle layer? You know, we’ve talked a lot about, I think, both ends right now, but in particular for that middle layer of this AI stack.
THOMAS: Well, I don’t think that it’s unique, but certainly they are the leader. They really were the starting place of that, and they just continue to build on their experience doing this. I mean, it’s a—it’s not something that AI can readily duplicate.
MATT: Right, that’s fair, too. And again, just be prepared for the volatility, I’m assuming, again, given the chart that we saw and you mentioned over the last year.
THOMAS: Absolutely.
MATT: Yeah. Last on the list, too, is MongoDB. Tell us about MongoDB in particular.
THOMAS: So Mongo is a database company, and to a certain degree—and they’re not strictly comparable—but the other two that people may be aware of are Snowflake and Datadog. You know, different businesses, but still sort of in the same orbit. And those two stocks have done very well and seem to be really considered to be AI winners, and Mongo has been more volatile. They did have their CEO leave for a very good position at Meta, and I think, you know, that brought the stock down a little bit. But they are at the beginning stages of positioning with the large language models, the frontier models, and positioning their database and the access to it, and the way that they label their data as particularly good for those and good for agents. And they’re just at the beginning stages of ramping that business with those frontier models. So we expect it to go from a smaller part of the business to a larger part of the business through rapid growth.
MATT: OK, so that rapid growth is there. I was also reading—what about the influence of India, too? Because I was reading that this week, too, at least expanding that part, and also into, you know, when it comes to customers, R&D and the like.
THOMAS: Right. Well, I mean, they’re looking at more geographies and can continue to just, you know, work with folks as they can.
MATT: Interesting stuff, too. And again, I just want to be clear, though, too, Thomas. And at this point, the software—you know, the software sector right now, you like these three picks, too. But as we’re seeing with what’s happening, too, with equities and, too, and we get into some of the Alphabets and some of the influence, we’re still seeing, you know, your overall sense of how much more volatile this is going to be moving forward here for the next, you know, short term, six months, a year, to long term, for the next few years.
THOMAS: Yeah, so AI has really made things to be very volatile because there are so many areas that it affects and that it can—it can do. So, I mean, we’ve seen that with Google’s earnings and with Microsoft’s earnings, is that these companies lap each other, and they’re spending money to get, you know, wherever there is first, and they—the positioning and the opportunity is huge, and we expect that that’s going to continue not just for the next six months or one year, but for several years. I mean, we’re really at the beginning of the usage and use cases for large language models and for AI in general. So that’s why we look for the ones that do have a large kind of installed base, a large capital base, access to capital and to good people, and that we think will be able to weather the storm through the ups and downs. So definitely, the—those leaders are the ones that we think will make it through to the other side.
MATT: Thomas, appreciate your time today on this. Thanks so much.
THOMAS: Great, thank you.
MATT: That’s Thomas Martin, senior portfolio manager at GLOBALT Investments.
| DISCLOSURE | PERSONAL | FAMILY | PORTFOLIO/FUND |
|---|---|---|---|
| PANW NYSE | N | N | Y |
| PLTR NASDAQ | N | N | Y |
| MDB NASDAQ | N | N | Y |
—
This BNN Bloomberg summary and transcript of the Oct. 29, 2026 interview with Thomas Martin are published with the assistance of AI. Original research, interview questions and added context was created by BNN Bloomberg journalists. An editor also reviewed this material before it was published to ensure its accuracy and adherence with BNN Bloomberg editorial policies and standards.
MMS • RSS

Most Viewed Stocks on Zacks.com
Based on total page views over the last 7 trading days
Trending Stocks on Zacks.com
Based on page view growth over the last 3 trading days
Top Articles

You are being directed to ZacksTrade, a division of LBMZ Securities and licensed broker-dealer. ZacksTrade and Zacks.com are separate companies. The web link between the two companies is not a solicitation or offer to invest in a particular security or type of security. ZacksTrade does not endorse or adopt any particular investment strategy, any analyst opinion/rating/report or any approach to evaluating individual securities.
If you wish to go to ZacksTrade, click OK. If you do not, click Cancel.
Back to top
document.logged_string = 0;
{
“@context”: “http://schema.org”,
“@type”: “BreadcrumbList”,
“itemListElement”: [
{
“@type”: “ListItem”,
“position”: 1,
“item”: {
“@id”: “https://www.zacks.com/stock/quote/MSFT”,
“name”: “Microsoft Corporation : (MSFT)”
}
}, {
“@type”: “ListItem”,
“position”: 2,
“item”: {
“@id”: “https://www.zacks.com/stock/news/3018793/microsoft-vs-mongodb-which-technology-stock-is-the-better-buy”,
“name”: “Microsoft vs. MongoDB: Which Technology Stock Is the Better Buy?”
}
}
]
}
{
“@context”: “http://schema.org”,
“@type”: “BreadcrumbList”,
“itemListElement”: [
{
“@type”: “ListItem”,
“position”: 1,
“item”: {
“@id”: “https://www.zacks.com/stock/quote/MDB”,
“name”: “MongoDB, Inc. : (MDB)”
}
}, {
“@type”: “ListItem”,
“position”: 2,
“item”: {
“@id”: “https://www.zacks.com/stock/news/3018793/microsoft-vs-mongodb-which-technology-stock-is-the-better-buy”,
“name”: “Microsoft vs. MongoDB: Which Technology Stock Is the Better Buy?”
}
}
]
}
var articleType = ‘B’;
var typeId = 6;
var categoryName = ‘Analyst Blog’;
var categoryId = 0;
var authorName = ‘Vasundhara Sawalka’;
var orgAuthorName = ‘Vasundhara Sawalka’;
var subCategoryName = ‘Analyst Blog : Most Popular Stocks’;
var datePosted = ‘October 29, 2026’;
var tickerList = ‘MSFT,MDB’;
Published in
var dataLayer = {
siteSection: ‘BLOG’
, loginStatus: ‘Logged out’
, siteType: ‘desktop’
, adidInternalCode : ‘DEF’
, pageIdentifier: “Microsoft vs. MongoDB: Which Technology Stock Is the Better Buy?”
, siteSubSection: ‘BLOG:Analyst Blog ‘
, session_id: ”
, ConfigID: ”
,tags : ‘artificial-intelligence,cloud-computing,tech-stocks’
, blogID: { name: ‘Microsoft vs. MongoDB: Which Technology Stock Is the Better Buy?’,
id: ‘3018793’,
author : ‘Vasundhara Sawalka’,
type : ‘blog’,
section : ‘Analyst Blog’,
sub_section : ‘Most Popular Stocks’,
tickers : [‘MSFT’,’MDB’],
publish_date : ’29/10/2026′,
rich_media : [‘HI,CT,GRA,KEY’]}
};
MMS • Bruno Couriol
Linearbytes released Bug0 QA Agent, a source-available Playwright library for agentic browser regression testing. The AI agent associates the test instructions expressed in natural language to actions on the user interface, caches those when appropriate for faster CI replays, remapping them to test specifications when the user interface changes. Verification is based on consensus from up to three LLMs and evaluations from vision models.
At one end of the spectrum, legacy approaches to web application testing, while largely automated, do not incorporate AI as a key productivity factor. At the other extremity, innovative teams follow a fully agent-based automated approach to testing where the agent is front and center, handling every browser interaction dynamically.
The legacy approaches often falls prey to known pain points. Test suites commonly depend on implementation details (CSS classes, attributes, data-testid) that may change even when the specifications remain constant, causing unnecessary test rewriting and refactoring. Flaky tests result from the inherently inpredictible nature of the complex, asynchronous and distributed systems underlying web applications (race conditions, latency, dropped calls).
AI-first testing approaches on the other hand suffer from high latency that makes them impractical for large regression suites. LLMs can routinely add several seconds of latency per step, escalate API token costs, and introduce their own brand of flakyness due to the non-determinism of the actions performed. On the bright side, test generation resists well to changes in the implementation; image and video models may provide visual verification with some success.
Bug0 proposes an hybrid approach in which its autonomous agent decouples the initial visual exploration from routine regression execution. Developers write declarative test steps in plain English inside standard Playwright specs.
test("Shopping cart tests", async ({ page }) => {
  await runSteps({
    page,
    test,
    expect,
    userFlow: "Add product to cart",
    steps: [
      { description: "Navigate to https://demo.vercel.store" },
      { description: "Click Acme Circles T-Shirt" },
      { description: "Select color", data: { value: "White" } },
      { description: "Select size", data: { value: "M" } },
      { description: "Add to cart", waitUntil: "My Cart is visible" },
    ],
    assertions: [{ assertion: "Cart shows the Acme Circles T-Shirt" }],
  });
});
During an initial execution, the agent inspects the accessibility tree and screenshots to understand the user interface and perform the requested actions. Once a single-action step executes successfully, the framework compiles the interaction into concrete browser operations and caches them into an in-memory Redis store. On following runs, the suite replays the cached action directly through Playwright, eschewing the latency cost of a new LLM inference.
When implementation details of the user interface change (e.g., button coordinates updated, form hierarchies modified), the replayed Playwright action may as a result throw an execution failure. Rather than failing the entire test run, Bug0 QA Agent detects the break, invalidates the action cache, and re-invokes the multimodal agent loop. Important caveat: caching applies only to single-action steps; complex, multi-action directives re-execute through the agent on every run.
Unlike action steps, assertion verification is not cached. Assertions execute through vision models on every pass. Claude and Gemini independently evaluate every assertion, with a third model breaking ties. Video models allow catching transient UI defects (e.g., auto-dismissing toast alerts, flashing banner errors).
The framework embeds disposable email testing via mailsink and community-built adapters like Mailinator, allowing tests to extract one-time passwords (OTPs) and magic links via natural language prompts like {{email.otp:Extract the 6-digit code}}.
Chevrot et al. (Are Autonomous Web Agents Good Testers?) reports that their best-performing autonomous testing architecture (ATA) agreed with human professional testers for only about 60% of test runs, identifying assertion verifiability and grounding (identification of the relevant elements of the target application for the test action) as primary drivers of improvement to scale usage of autonomous testing agents. The paper was published in April 2025 and used GPT-4o, Sonnet, and Gemini. As language models and harnesses regularly improve, so do the efforts to use AI to improve the productivy of testing in all its aspects (generation, self-healing, execution, triage, analytics).
Bug0 QA Agent is released under the Functional Source License, Version 1.1, ALv2 Future License. The Functional Source License is a source-available license (i.e., not open-source), that imposes non-compete restrictions during the first two years of usage. The license came of existence to, in the words of Sentry, its first proponent, “grant freedom without harmful free-riding.”
MMS • RSS
MongoDB公司(MDB-US)截至台北時間29日21:33股價下跌20.57美元,報372.87美元,跌幅5.23%,成交量44,605(股),盤中最高價379.00美元、最低價372.82美元。
美股指數盤中表現
- 道瓊指數:-0.43%
- S&P 500指數:-0.55%
- NASDAQ指數:-1.61%
- 費城半導體指數:-2%
MongoDB公司(MDB-US)歷史漲跌幅
- 近 1 週:+0.69%
- 近 1 月:+17.56%
- 近 3 月:+26.66%
- 近 6 月:+52.38%
- 今年以來:-6.25%
更多鉅亨報導
MMS • RSS
Most Viewed Stocks on Zacks.com
Based on total page views over the last 7 trading days
Trending Stocks on Zacks.com
Based on page view growth over the last 3 trading days
Top Articles
You are being directed to ZacksTrade, a division of LBMZ Securities and licensed broker-dealer. ZacksTrade and Zacks.com are separate companies. The web link between the two companies is not a solicitation or offer to invest in a particular security or type of security. ZacksTrade does not endorse or adopt any particular investment strategy, any analyst opinion/rating/report or any approach to evaluating individual securities.
If you wish to go to ZacksTrade, click OK. If you do not, click Cancel.
Back to top
auto_ad = -1;
article_id = 3018417;
var articleCta = articleCta || {};
articleCta.articleId = ‘3018417’;
articleCta.datePosted = ‘102926’;
articleCta.articleType = ‘BLOG’;
articleCta.articleIsAi = ‘N’;
articleCta.primaryTickerAndCompanyName = `MDB:MongoDB, Inc.`;
articleCta.placementDate = ‘2026-10-29’;
articleCta.categoryId = ‘155’;
articleCta.authorId = ‘631459560’;
articleCta.subCategoryName = ‘Press Releases’;
articleCta.indiaFlag = ‘N’;

Image: Shutterstock
Read MoreHide Full Article
For Immediate Release
Chicago, IL – October 29, 2026 – Today, Zacks Equity Research discusses MongoDB (MDB – Free Report) , Affirm (AFRM – Free Report) and Elastic (ESTC – Free Report) .
Industry: Internet Services
The Zacks Internet Software industry players like MongoDB, Affirm and Elastic are benefiting from rapid adoption of AI, which is expanding software usage. AI is driving higher platform engagement, broader enterprise adoption and new monetization opportunities. The transition from traditional generative AI applications to autonomous AI agents is emerging as a significant growth driver for industry players.
Enterprises are increasingly seeking platforms that enable AI agents to access real-time operational data, execute complex workflows and automate decision-making. Growing adoption of generative AI is increasing the importance of vector search, semantic retrieval, embedding models and hybrid search technologies. The proliferation of AI applications, cloud-native workloads and distributed infrastructure is increasing the complexity of software performance monitoring.
Industry Description
The Zacks Internet Software industry comprises companies offering application performance monitoring, infrastructure and application software, DevOps deployment and Security software. Industry participants offer online payment solutions, asset optimization software, multi-cloud application security and delivery, social networking, 3D printing applications, and cloud content management solutions.
They use the SaaS-based cloud computing model to deliver solutions to end-users, as well as enterprises. As a result, subscriptions are the primary revenue source. Advertising is also a major revenue source. Industry participants target a variety of end markets, including banking and financial services, construction, consumer packaged goods, education, energy, legal, various service providers, federal governments, and animal health technology and services.
3 Trends Shaping the Future of the Internet Software Industry
Enterprise Software Infrastructure Growing Rapidly: The industry is benefiting from rapid AI adoption, which is driving demand for enterprise software infrastructure. AI-generated code is driving sharp increases in code pushes and platform usage, creating structural demand for DevSecOps platforms that can manage security, governance and deployment at machine scale.
The growing requirement for integrated platforms capable of orchestrating both human developers and AI agents, while maintaining compliance and operational control, is benefiting the industry’s prospects. Platform consolidation is becoming increasingly attractive as enterprises seek unified data and AI infrastructure.
Consumption-Based Pricing Gains Traction: The emergence of AI-native pricing models is a key catalyst. The industry players are moving beyond traditional seat-based licensing by introducing consumption-based credits and outcome-driven pricing. The companies are allowing customers to scale usage as AI adoption expands, opening new monetization channels that extend beyond conventional software subscriptions. AI-powered agents, automation and consumption-based pricing are creating incremental revenue streams while increasing customer productivity.
AI Agents & AI-Workloads Create Opportunities: The growing need to secure cloud platforms amid the increasing risks of cyberattacks and hacking drives the demand for web-based cybersecurity software. As enterprises continue to move their on-premises workloads to cloud environments, application and infrastructure monitoring are gaining importance. This is increasing the demand for web-based performance management monitoring tools. AI applications, AI agents and cloud-based AI workloads are expanding the attack surface for businesses, which bodes well for industry participants.
Zacks Industry Rank Indicates Bright Prospects
The Zacks Internet Software industry, placed within the broader Zacks Computer and Technology sector, carries a Zacks Industry Rank #80, which places it in the top 32% of more than 247 Zacks industries.
The group’s Zacks Industry Rank, which is the average of the Zacks Rank of all the member stocks, indicates bright near-term prospects. Our research shows that the top 50% of the Zacks-ranked industries outperform the bottom 50% by a factor of more than two to one.
The industry’s position in the top 50% of the Zacks-ranked industries is the result of a positive earnings outlook for the constituent companies in aggregate. Looking at the aggregate earnings estimate revisions, it appears that analysts are optimistic about this group’s earnings growth potential. The industry’s earnings estimates for 2026 have moved north by 2.4% since July 31, 2026.
Given the bullish outlook of the industry, there are a number of stocks worth picking for healthy portfolio returns. However, before we present the top industry picks, it is worth looking at the industry’s shareholder returns and current valuation first.
Industry Lags S&P 500 and Sector
The Zacks Internet Software industry has underperformed the broader Zacks Computer and Technology sector and the S&P 500 Index in the past year.
The industry has dropped 11% over this period compared with the S&P 500’s jump of 12.2% and the broader sector’s appreciation of 12.1%.
Industry’s Current Valuation
On the basis of forward 12-month price-to-sales (P/S), which is a commonly used multiple for valuing Internet Software stocks, we see that the industry is currently trading at 4.03X compared with the S&P 500’s 4.55X and the sector’s forward 12-month P/S of 5.57X.
Over the last five years, the industry has traded as high as 6.54X and as low as 3.22X, with a median of 4.82X.
3 Internet Software Stocks to Buy Right Now
MongoDB: This Zacks Rank #1 (Strong Buy) stock is benefiting from growing demand for its Atlas cloud database platform, driven by enterprise modernization and increasing adoption of AI applications. You can see the complete list of today’s Zacks #1 Rank stocks here.
Growing adoption of Atlas Vector Search, Voyage AI Embeddings and the managed Model Context Protocol (MCP) Server is strengthening MongoDB’s position in agentic AI applications. Increasing demand from AI-native companies and frontier AI laboratories is expected to create additional growth opportunities. MongoDB’s prospects are benefiting from growing demand for its Enterprise Advanced (EA) solutions, particularly across financial services, technology and government organizations.
MongoDB shares have dropped 33.7% year to date (YTD). The Zacks Consensus Estimate for 2026 earnings has inched up by a penny to $1.04 per share over the past 30 days.
Affirm: Another Zacks Rank #1 company, Affirm is benefiting from growing adoption of its buy now, pay later (BNPL) solutions among online merchants and consumers. The company is currently available on 80 of the top 250 e-commerce websites, highlighting significant opportunities for further merchant penetration. Expanding relationships with major payment service providers, growing merchant integrations and increasing consumer preference for flexible payment options are expected to support gross merchandise volume (GMV) growth.
Affirm’s growth prospects are benefiting from increasing adoption of the Affirm Card and expansion into offline commerce. Consumers using the Affirm Card spend approximately twice as much as average Affirm consumers, highlighting the product’s potential to drive higher engagement and transaction volumes.
Affirm shares have dropped 48.9% YTD. The Zacks Consensus Estimate for its 2026 earnings is pegged at $13.11 per share, down by a penny in the past 30 days.
Elastic: This Zacks Rank #1 company is benefiting from growing demand for AI-powered search and cybersecurity solutions as enterprises increasingly deploy generative and agentic AI applications. The company’s Elasticsearch platform supports text, vector and hybrid search capabilities, enabling organizations to retrieve accurate information from structured and unstructured datasets.
The introduction of VectorDB index mode, Jina embedding and reranking models, and enhancements to Agent Builder is strengthening Elastic’s competitive positioning. Growing demand for AI-powered search, enterprise knowledge retrieval and automated security operations is expected to drive subscription revenue growth and customer expansion.
Elastic shares have dropped 16.4% YTD. The Zacks Consensus Estimate for ESTC’s fiscal 2027 earnings is pegged at 81 cents per share, unchanged over the past 30 days.
Free: Instant Access to Zacks’ Market-Crushing Strategies
Since 2000, our top stock-picking strategies have blown away the S&P’s +7.7% average gain per year. Amazingly, they soared with average gains of +48.4%, +50.2% and +56.7% per year.
Today you can tap into those powerful strategies – and the high-potential stocks they uncover – free. No strings attached.
Join us on Facebook: https://www.facebook.com/ZacksInvestmentResearch/
Zacks Investment Research is under common control with affiliated entities (including a broker-dealer and an investment adviser), which may engage in transactions involving the foregoing securities for the clients of such affiliates.
Media Contact
Zacks Investment Research
800-767-3771 ext. 9339
Past performance is no guarantee of future results. Inherent in any investment is the potential for loss. This material is being provided for informational purposes only and nothing herein constitutes investment, legal, accounting or tax advice, or a recommendation to buy, sell or hold a security. No recommendation or advice is being given as to whether any investment is suitable for a particular investor. It should not be assumed that any investments in securities, companies, sectors or markets identified and described were or will be profitable. All information is current as of the date of herein and is subject to change without notice. Any views or opinions expressed may not reflect those of the firm as a whole. Zacks Investment Research does not engage in investment banking, market making or asset management activities of any securities. These returns are from hypothetical portfolios consisting of stocks with Zacks Rank = 1 that were rebalanced monthly with zero transaction costs. These are not the returns of actual portfolios of stocks. The S&P 500 is an unmanaged index. Visit https://www.zacks.com/performance for information about the performance numbers displayed in this press release.
document.logged_string = 0;
{
“@context”: “http://schema.org”,
“@type”: “BreadcrumbList”,
“itemListElement”: [
{
“@type”: “ListItem”,
“position”: 1,
“item”: {
“@id”: “https://www.zacks.com/stock/quote/MDB”,
“name”: “MongoDB, Inc. : (MDB)”
}
}, {
“@type”: “ListItem”,
“position”: 2,
“item”: {
“@id”: “https://www.zacks.com/stock/news/3018417/zacks-industry-outlook-highlights-mongodb-affirm-and-elastic”,
“name”: “Zacks Industry Outlook Highlights MongoDB, Affirm and Elastic”
}
}
]
}
{
“@context”: “http://schema.org”,
“@type”: “BreadcrumbList”,
“itemListElement”: [
{
“@type”: “ListItem”,
“position”: 1,
“item”: {
“@id”: “https://www.zacks.com/stock/quote/ESTC”,
“name”: “Elastic N.V. : (ESTC)”
}
}, {
“@type”: “ListItem”,
“position”: 2,
“item”: {
“@id”: “https://www.zacks.com/stock/news/3018417/zacks-industry-outlook-highlights-mongodb-affirm-and-elastic”,
“name”: “Zacks Industry Outlook Highlights MongoDB, Affirm and Elastic”
}
}
]
}
{
“@context”: “http://schema.org”,
“@type”: “BreadcrumbList”,
“itemListElement”: [
{
“@type”: “ListItem”,
“position”: 1,
“item”: {
“@id”: “https://www.zacks.com/stock/quote/AFRM”,
“name”: “Affirm Holdings, Inc. : (AFRM)”
}
}, {
“@type”: “ListItem”,
“position”: 2,
“item”: {
“@id”: “https://www.zacks.com/stock/news/3018417/zacks-industry-outlook-highlights-mongodb-affirm-and-elastic”,
“name”: “Zacks Industry Outlook Highlights MongoDB, Affirm and Elastic”
}
}
]
}
var articleType = ‘B’;
var typeId = 57;
var categoryName = ‘Press Releases’;
var categoryId = 0;
var authorName = ‘Zacks Equity Research’;
var orgAuthorName = ‘Santanu Roy ‘;
var subCategoryName = ‘Press Releases’;
var datePosted = ‘October 29, 2026’;
var tickerList = ‘MDB,ESTC,AFRM’;
Published in
var dataLayer = {
siteSection: ‘BLOG’
, loginStatus: ‘Logged out’
, siteType: ‘desktop’
, adidInternalCode : ‘DEF’
, pageIdentifier: “Zacks Industry Outlook Highlights MongoDB, Affirm and Elastic”
, siteSubSection: ‘BLOG:Press Releases’
, session_id: ”
, ConfigID: ”
,tags : ‘computers,internet’
, blogID: { name: ‘Zacks Industry Outlook Highlights MongoDB, Affirm and Elastic’,
id: ‘3018417’,
author : ‘Zacks Equity Research’,
type : ‘blog’,
section : ‘Press Releases’,
sub_section : ”,
tickers : [‘MDB’,’ESTC’,’AFRM’],
publish_date : ’29/10/2026′,
rich_media : [‘HI’]}
};
MMS • Ben Linders
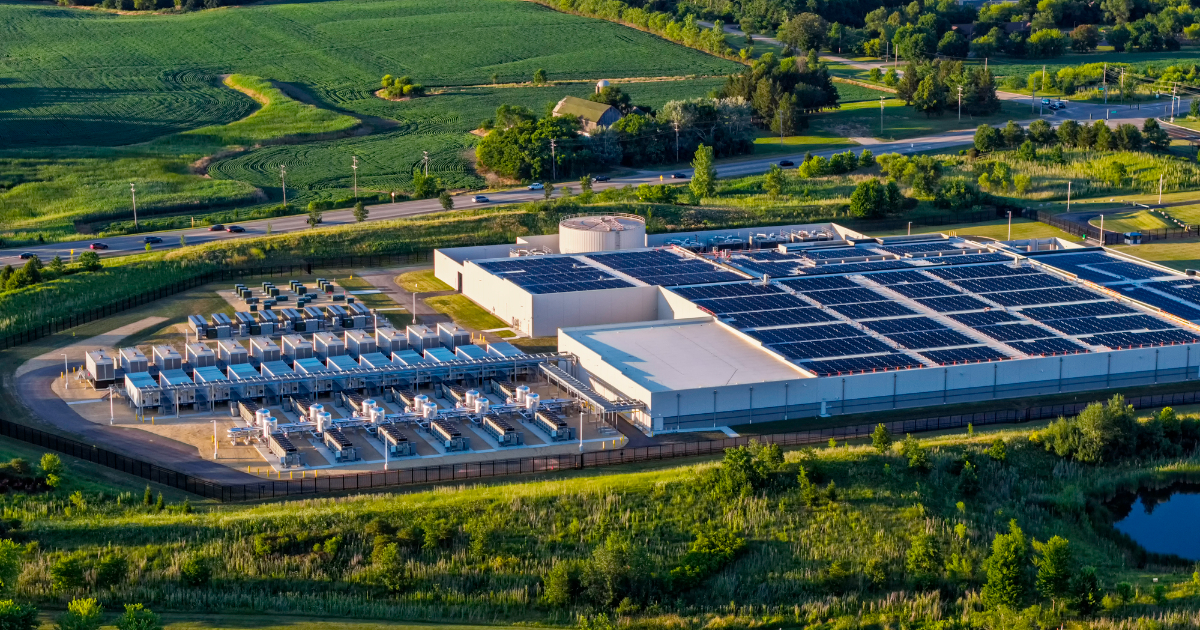
IT is responsible for about 2 – 4% of all global emissions, and electricity use at Microsoft and Google has climbed because of AI, according to their own reports. Charles Humble spoke about Green AI at GOTO Copenhagen, where he argued sustainability ought to be a top-level architectural concern. Amongst his recommendations: use pre-built and smaller models, run compute where low-carbon electricity is abundant, and train on renewable energy.
Humble quoted the International Energy Agency (IEA), which has stated that the combined electricity use from Amazon, Microsoft, Google, and Meta has more than doubled between 2017 and 2021, rising to around 72 terawatt-hours in 2021. Microsoft’s 2024 environmental report mentioned that its total carbon emissions have risen 30% since 2020, primarily due to the construction of data centers to meet demand for AI. Google’s emissions had surged about 50% since 2019 and 13% year on year in 2023 alone, according to their own reporting, largely driven by artificial intelligence.
The emission that these reports talk about is mainly carbon dioxide, a greenhouse gas. Since the Industrial Revolution we’ve been increasing the concentration of greenhouse gases in the atmosphere, trapping more heat, Humble said. We want to keep our warming to 1.5 degrees by 2100, but projections suggest that it will be between about 2.5 and 3 degrees.
The IT industry contributes a lot to this problem, partly through electricity use as Humble explained:
The IEA estimated that global data centre electricity consumption in 2022 is about 240 to 340 terawatt hours, 1 to 1.3% of global electricity demand. Networks add another 260 to 360 terawatt hours. That’s 700 terawatt hours, about the same as Brazil’s 726 terawatt hours in the same time period.
IT is responsible for about 2 – 4% of all global emissions, where aviation is 3%, Humble said. But while the aviation industry is working quite hard to try and cut its emissions, we as an industry are doing the opposite.
There are several questions Humble suggested asking for putting AI into a business context:
- Do you really need it?
- Do you need to train a new model from scratch, or can you use a pre-built one?
- If you can relax part of your SLA, does that allow you to run your workloads in a greener location?
- Can you use demand shaping?
If we need to train a custom model, Humble suggested thinking about how much data we actually need to collect. Sometimes, smaller models work better, he argued. He also suggested using open-source data sets and, if possible, demand shifting to collect data when and where there is green energy available.
In theory, training can be on 100% renewable energy all the time, which can reduce carbon emissions somewhere between 45% and 99%, Humble mentioned.
He argued that most of the energy may actually be spent when we deploy a model into production and maintain it, and mentioned four steps to make all computing greener:
- Use the smallest hardware configuration that can safely execute the job.
- Run compute in areas where low-carbon electricity is abundant and where there are credible plans to make the grid even cleaner.
- Use cloud services from cloud providers that have data centers in green locations and provide good tooling to help reduce your footprint.
- Optimize the execution time of jobs to further reduce the carbon footprint.
Sustainability ought to join cost, performance, security, regulatory concerns, and reliability as one of the top-level considerations for your computing workloads, Humble concluded. We should think about how to build systems in a more environmentally sound way.
InfoQ interviewed Charles Humble after his talk.
InfoQ: How does location matter when it comes to reducing carbon emissions?
Charles Humble: A compute workload uses a fixed amount of energy, but the carbon cost of that energy varies enormously by place and time depending on the sources of electricity that is powering the data centre. Assuming the data centre is using grid power in a region running mostly on hydro, solar, nuclear and wind (for example Norway, Sweden and France), running a workload here can be many times cleaner than one dependent on coal or gas. Carbon intensity also changes during the day and over the course of the year as wind, solar and demand vary.
In carbon aware computing we can apply a technique called demand shifting based on this. Demand shifting can be done in one of two ways, either time or location based. Time-based is particularly applicable when a use case isn’t latency sensitive, such as AI training.
For location the most simple variation of the technique is to just pick lower-carbon regions by default for new, latency-tolerant workloads. More advanced variations might involve moving to different hemispheres seasonally to maximize exposure to sunlight and solar power.
InfoQ: How does demand shaping work?
Humble: Demand shaping means changing how much work your software does, or what kind of work, in response to how clean or constrained the electricity supply is at that moment. One version of this is to give users a choice. For an AI-powered service, you could let users choose to talk to a person instead of the AI up front, or at any point during the process.
You can also apply techniques such as graceful degradation based on higher carbon intensity, for example by serving lower-quality video or images, turning off autoplay, skipping non-essential animations, or reducing refresh rates. You might also use a smaller model.
Tradeoffs include increased complexity, and of course you have to determine if the reduced service is still acceptable.
InfoQ: What can we do to make model training greener?
Humble: Alongside demand shifting for both training and data collection, avoid training from scratch if at all possible. Use a pre-trained model and fine-tune it, or just prompt it and/or use Retrieval-Augmented Generation (RAG) if that meets the need.
Shrinking the model size can speed up training and improve efficiency. Distillation, quantization and pruning can all be used for compression. On-device training via Federated learning can be greener in some cases. Keep in mind that for widely used models, inference over the model’s lifetime may cause greater total emissions, so efficiency in serving matters too.
Raghavendra Selvan’s book “Sustainable AI” explores a number of these approaches in considerably greater depth, so if readers want to learn more, this is a great resource.
QCon AI New York 2026 Program Committee Picks: Agent Identity, Context Costs, and Open-Source Infere
MMS • Artenisa Chatziou
Who authorizes an agent’s actions? How should teams manage growing context costs? What changes when coding agents become part of everyday engineering work? The QCon AI New York 2026 program committee has selected six sessions they are looking forward to at the December 15–16 conference. Their picks examine these questions alongside open-source inference, agent standards, and audio AI.
Conference chair Hien Luu, an AI/ML leader, advisor, speaker, and author, joins committee members Wes Reisz, Technical Principal at Thoughtworks and creator of The InfoQ Podcast, and Faye Zhang, Staff Engineer at Google building autonomous agents for Gemini Enterprise, in sharing their selections.
Wes on Agent Identity and Context Costs
Wes Reisz selected When Software Becomes a User: Identity and Authorization for Agents in Production, a keynote by Nancy Wang, CTO at 1Password.
As agents take on more autonomous work, traditional identity and authorization models start to break down. Nancy will explore delegated authority, credential management, and securing agent interactions, foundational capabilities I believe we must get right to truly adopt agentic delivery.
Nancy’s keynote examines how authority is delegated across subagent chains and how agents can access the credentials they need without exposing secrets in their context.
Wes’s second choice is Make Each Token Count: Compression, Caching, and Retrieval for Production LLM Context, by Tejas Chopra, CEO and co-founder of Headroom Labs.
Token costs and latency are real constraints when building production agents. Tejas will explore compression, caching, and retrieval strategies, particularly token compression, which I believe will become a must-have capability in modern agentic systems.
Tejas will cover learned prompt compression, prefix-cache-aware context alignment, and compress-cache-retrieve pipelines, including failure modes that affect tool calling and agent trajectories.
Hien on Engineering Organizations and Open-Source Inference
Hien Luu selected The Future of the Engineering Org, by Peter Bell, founder and CTO of Gather.dev.
Drawing on conversations with engineering leaders at organizations including Anthropic, OpenAI, Shopify, and Coinbase, Peter will examine how engineering structures and practices are changing around coding agents. Topics include team size and rituals, hiring and assessing engineers, changes in engineering leadership, and the future of junior developers.
Hien’s second pick is Open Source Agentic Inference: Unlocking the Harness with vLLM, by Francisco Javier Arceo, Forward Deployed Engineer at Baseten and maintainer of the vLLM Agentic API project.
Francisco will follow a coding task from the harness through model generation, tool execution, and continuation using Agentic API, vLLM, and llm-d. The session examines where tools run, who owns context, and how serving infrastructure supports these workloads. It also explores how repeated inference and context growth affect cost, including why cost per completed task matters more than token price alone.
Faye on Agent Standards and Audio AI
Faye Zhang described her selections as “two talks at the intersection of frontier research and production engineering”. Her first choice is Navigating Agentic Standards: What to Build On Now and What to Watch, by Kevin Kelley, Technical Lead for Standards at Anthropic.
She also highlighted how standards such as MCP, A2A, and OAuth can establish interoperable agent identity, delegated authorization, and trust boundaries without creating new security vulnerabilities. Kevin’s session organizes the standards landscape around questions such as which agent is acting, on whose behalf, and how it reaches tools and other agents. It distinguishes what has shipped from work that remains open.
Her second selection is Audio Processing with Large Language Models, a keynote by Tara Sainath, Distinguished Research Scientist at Google DeepMind and lead of the Gemini audio area.
Faye highlighted the questions raised by LLMs reshaping speech and audio modeling: unified multilingual representations, end-to-end versus cascaded architectures, and the latency–quality trade-offs required for real-time conversational intelligence. Tara’s keynote will discuss research and product developments at Google across speech recognition, generation, translation, and dialogue.
Early-Bird Pricing Changes November 10
QCon AI New York 2026 takes place December 15–16 at the Westin Jersey City Newport, one PATH stop from Lower Manhattan. The two-day conference focuses on production AI for senior software engineers, architects, and engineering leaders.
Early-bird pricing is $1,705 until November 10, after which the two-day pass rises to $1,790. Anyone planning to use their remaining 2026 learning and development budget can explore the QCon AI New York program and the “convince your manager” approval email on the conference website.
Anthropic Says Nobody Needs a Mental Model of Claude Code. Practitioners Are Testing That
MMS • Steef-Jan Wiggers
Anthropic has published how the Claude Code team runs code review now that Claude writes about 90% of Claude Code itself. The claim drawing the most scrutiny is not the percentage but what the team says it no longer needs.
The post, by Addy Osmani, Morgan Westlee Lunt and Qing Wang, is the companion to Anthropic’s account of replacing git with an in-house system after its monorepo went from roughly 2,500 merged changes a day in May to more than 30,000 in September. Review was the next thing to break. The target is that most pull requests “merge with at most one human in the loop, who can be the author, with no increase in reverts or incidents.”
On comprehension, the team is explicit:
Nobody on the team keeps a complete mental model of Claude Code in their head, and we don’t think anyone needs to. When someone wants to understand a part of the codebase, they ask Claude to write an explainer for exactly that slice. It takes minutes and reflects the code as it is today.
That passage dominated the Hacker News discussion, where commenter jonahx set out what it trades away:
There is no longer anyone to turn to if this system breaks by, eg, having a critical bug that no one can figure out. No causal model in anyone’s head that can be appealed to, to slowly and methodically debug. The new trust model is: We trust Claude to always understand the system enough to debug anything or make any reasonable change we could want.
He also noted that many large legacy systems already work this way.
One documented case tests the explainer claim on Anthropic’s own repository. In August, Claude Code collaborator Boris Cherny answered a long-running complaint about issue auto-closure in a comment carrying the “Generated with Claude Code” footer. It said issues are closed when they have “had no activity for a while and are missing information needed to reproduce,” and that “nothing is triaged solely by counting.”
The repository’s issue-lifecycle.ts sets fourteen days to stale and fourteen more to closure, exempting only issues with ten or more upvotes. Developer marcindulak counted more than 6,000 issues labelled as carrying reproduction steps that were closed anyway as “inactive for too long.” The remedy the comment offered, commenting to have an issue reopened, is blocked by a workflow that locks closed issues after seven days. That meta-issue is now locked.
The answer that started this issue, and misdiagnosed how issues in this repo are managed, was generated by a world-class model.
The failures the post documents are specific. The first appears only when both sides are machines:
Noise costs more when the author is an agent. A person can wave off a nit in seconds. An agent fixes it, which means another commit and another round of review.
“One CLI PR went through more than fifty rounds of review and fixes overnight before its author stopped it,” the team writes. Running more rounds by default made things worse, so they capped them. On r/ClaudeCode, commenter ChemicalExcellent463 reported reaching the same control independently, stopping after two failed fixes because repeated failure means the agent’s picture of the code is wrong rather than the line it keeps editing.
The second failure is what those rounds were finding:
When we ran git blame on what the reviewer kept flagging, about 59% of it was code that had been there since the reviewer’s first pass. The reviewer was rarely finding new bugs, it was finding a few more old ones each round.
What gates a merge is a risk tier picked by a classifier, where “the change sets the tier, not the author.” Low risk covers docs, copy, and additive changes behind a flag, and clears with no human approval. Medium risk, including caching, the auto-updater, and system prompts, needs one person. Two rules hold the line: “an agent’s approval never counts as a person’s,” and the person who prompted a change “counts as one of the required reviewers.”
That boundary drew a question the post does not answer. Reddit commenter Oximy-Naman asked whether low risk covers agent instruction changes shipped as documentation, since those “could change what an agent does without touching application code,” and got no reply. The post assigns no tier to CLAUDE.md, the file its own reviewer loads on every review. On compliance, Hacker News commenter gaal_dornick reported that their own SOC 2 reviewer required every change to be seen by a second human before production; the post does not discuss audit requirements.
One control is missing, and the team says so:
We don’t yet have circuit breakers that tighten approval when those numbers move; engineers here want them before more code moves to zero-human merges.
Not everyone reads this as reckless. Commenter cheema33 argued that large organizations have never had anyone holding a complete model, making this an upgrade on the status quo, and commenter markbao reported spending a few thousand dollars a month on AI review against human review that consumes up to a third of an engineer’s time.
Parts of the system ship publicly. Code Review for Claude Code is generally available on Team and Enterprise plans, and the security review runs as an open-source GitHub Action whose README states that it “is not hardened against prompt injection attacks and should only be used to review trusted PRs.”
MMS • Renato Losio
Cloudflare has recently launched a beta Web Search API through AI Gateway. Available through REST APIs and Cloudflare Workers, it provides unified logging, access controls, and billing, and supports bring-your-own-provider keys.
The API enables AI agents to retrieve live web results from Ceramic.ai, Exa, and Linkup. It provides a unified interface, integrates search billing with AI Gateway, logs search requests alongside model inference, and requires providers to follow verified-bot requirements and return source links.
Cloudflare’s Web Search API allows AI applications to retrieve current web content, including recent news, API changes, and technical documentation, and provide the results as context to language models during inference. Michelle Chen, group product manager at Cloudflare, Sam Else, senior director at Cloudflare, and Gabriel Massadas, senior systems engineer at Cloudflare, explain the challenge that the company is trying to address:
When you use an agent and it needs to fetch a live web page, the agent usually just guesses the URL of the page and then makes a tool call to curl it. This is why you’ll sometimes see web fetches come back with a 404 Not Found, which happens if the agent incorrectly guesses the URL of that information. As you can imagine, it’s not super efficient to randomly guess URLs all the time.
Applications and external services can access web search through a REST endpoint by providing an AI Gateway authentication token and specifying a search provider in the request payload, with the endpoint returning the search results. Chen, Else, and Massadas add:
The crawler used by the web search provider must comply with Cloudflare’s publicly stated requirements for “Verified bots” as defined in our developer documentation, and web search responses must include a link to the location of crawled content. These rules are net-positive for a fair Internet, and allow creators to decide what they want to do with their data.
In a popular Hacker News thread, the community discusses search quality, data-retention restrictions, and whether a unified API offers meaningful advantages over existing alternatives. Simon Willison writes:
My number one question about search APIs is always if they allow you to store and resyndicate results you get from them. If I’m running an agent system but I’m not allowed to store the responses – or provide a “share transcript” button – that’s a pretty significant limitation. The answer to that question is inevitably buried deep in the terms.
Maximilian Goisser, CTO and co-founder of Erato Labs, notes:
I think Cloudflare is (for companies already using it) approaching the status of trusted main cloud supplier (which usually would be AWS, GCP, Azure) via which the majority of cloud costs are billed (so you don’t have to go through a fresh procurement process).
Cloudflare states it will identify providers that support Zero Data Retention and offers search at providers’ list prices without additional markup. The company plans to add native server tools to AI Gateway, starting with web search. Until then, developers can integrate web search into their workflows using Cloudflare Workers.
auto_ad = -1;
article_id = 3018793;
var articleCta = articleCta || {};
articleCta.articleId = ‘3018793’;
articleCta.datePosted = ‘102926’;
articleCta.articleType = ‘BLOG’;
articleCta.articleIsAi = ‘N’;
articleCta.primaryTickerAndCompanyName = `MSFT:Microsoft Corporation`;
articleCta.placementDate = ‘2026-10-29’;
articleCta.categoryId = ‘292’;
articleCta.authorId = ‘3973844’;
articleCta.subCategoryName = ‘Analyst Blog : Most Popular Stocks’;
articleCta.indiaFlag = ‘Y’;
Image: Bigstock
Microsoft vs. MongoDB: Which Technology Stock Is the Better Buy?
Key Takeaways
Microsoft (MSFT – Free Report) and MongoDB (MDB – Free Report) are both positioning their platforms at the center of enterprise artificial intelligence (AI) adoption. Microsoft monetizes AI through Azure, Foundry and Copilot, while MongoDB powers AI applications through its Atlas platform and Enterprise Advanced offering.
The two also compete directly, as Microsoft’s PostgreSQL, SQL Database and Cosmos DB services vie with MongoDB for the operational data workloads that feed AI agents. With both updating outlooks and launching agentic AI tools, the comparison is timely.
Let’s delve deep and closely compare the fundamentals of the two stocks to determine which one is a better investment now.
The Case for MSFT Stock
Microsoft’s AI strategy is gaining traction as its business model expands from per-seat subscriptions to consumption-based pricing. In October 2026, the company introduced the new Copilot, unifying Chat, Cowork, Autopilot and code in one experience, brought Office into the Copilot app and made Microsoft 365 E7 and Agent 365 generally available. At GitHub Universe, it launched Copilot Fusion, which routes coding tasks across multiple models. Commercial remaining performance obligation of $677 billion provides solid long-term revenue visibility.
For the second quarter of fiscal 2027, Microsoft expects revenues of $96-$97.1 billion, indicating 18-19% year-over-year growth. Azure revenues are expected to grow 49-50% in constant currency, while Microsoft 365 Commercial Cloud is projected to grow roughly 19%.
However, this growth comes at a steep cost. Microsoft expects second-quarter capital expenditure to exceed $50 billion, with 2026 spending of approximately $170 billion and further acceleration in the second half of fiscal 2027. Demand continues to exceed available supply, and some third-party GPU capacity deliveries have been pushed to the second half. Microsoft Cloud gross margin is expected to decline to roughly 65% due to a higher Azure mix, while operating margin is expected to dip slightly year over year.
The Devices and Consumer business remains a drag, with Windows OEM and devices revenues expected to decline in the mid-30s percent range due to elevated inventory, weak PC demand and a tough Windows 10 comparison. Although free cash flow is expected to stay positive in fiscal 2027, rising capital intensity limits near-term upside.
The Zacks Consensus Estimate for MSFT’s fiscal 2027 earnings is pegged at $19.66 per share. The estimate indicates 9.53% year-over-year growth.
Microsoft Corporation Price and Consensus
Microsoft Corporation price-consensus-chart | Microsoft Corporation Quote
The Case for MDB Stock
MongoDB is emerging as the intelligent data platform for the AI era. At its Investor Day on Sept. 29, 2026, the company launched MongoDB 9.0, delivering up to 2x higher throughput, along with Atlas Infinite, a new deployment option that separates compute from storage for AI-scale demand and Atlas Agent Engine, which unifies governance, memory and retrieval for running AI agents in production. MongoDB also launched the Atlas Managed MCP Server, connecting coding agents to live Atlas data, and made Search and Vector Search generally available in Enterprise Advanced.
These innovations are backed by a strong outlook. MongoDB raised its fiscal 2027 guidance and now expects revenues of $2.99-$3.03 billion, non-GAAP operating income of $616.3-$636.3 million and non-GAAP earnings of $6.39-$6.58 per share, with the second-half raise mainly driven by Atlas. For the third quarter, revenues are expected to be in the range of $756-$761 million.
At Investor Day, MongoDB also raised its long-term targets, now aiming for 20%+ total revenue growth and mid-20% Atlas growth over roughly three years, along with 100-200 basis points of average annual operating margin expansion. Remaining performance obligations surged 91% year over year to $1.52 billion, reflecting rising multi-year commitments.
MongoDB’s asset-light model is a key advantage, as it does not shoulder Microsoft-scale capital spending. With $2.4 billion in cash and investments, the company continues to actively repurchase its shares.
The Zacks Consensus Estimate projects 2026 earnings of $6.50 per share, representing a substantial 30.78% year-over-year growth. The earnings estimates have been revised upward over the past 30 and 60 days.
MongoDB, Inc. Price and Consensus
MongoDB, Inc. price-consensus-chart | MongoDB, Inc. Quote
Valuation and Price Performance Comparison
Both MSFT and MDB trade at premium valuations. In terms of forward 12-month Price/Sales (P/S), MSFT trades at 9.52X, while MDB trades at 9.19X. MDB’s premium is justified as its guidance calls for 20%+ long-term revenue growth, steady margin expansion and minimal capital spending, while MSFT’s multiple already prices in AI optimism amid soaring capital expenditure and margin pressure, making it prudent to wait.
MSFT vs. MDB: P/S F12M Ratio
Image Source: Zacks Investment Research
On price performance, MSFT shares have returned 9.8% over the year-to-date period, while MDB shares have lost 6.3%. MDB’s pullback offers investors an attractive entry point, as its raised long-term targets signal that fundamentals remain intact.
MSFT Outperforms MDB Year to Date
Image Source: Zacks Investment Research
Conclusion
MongoDB holds an edge over Microsoft on several fronts. MDB benefits from a raised fiscal 2027 outlook, upgraded long-term targets of 20%+ revenue growth, expanding margins and an asset-light model that converts growth into free cash flow. Recent launches, including MongoDB 9.0, Atlas Infinite and Atlas Agent Engine, strengthen its AI positioning, while a lower forward P/S multiple and year-to-date share price decline offer a compelling entry point. Microsoft’s AI momentum is solid, but soaring capital expenditure, declining cloud gross margin and Windows weakness limit upside. Investors should buy MDB now and wait for a better entry point for MSFT. MSFT currently carries a Zacks Rank #3 (Hold), whereas MDB has a Zacks Rank #2 (Buy). You can see the complete list of today’s Zacks #1 Rank (Strong Buy) stocks here.